Good morning. Here is what matters in AI today, and how to put it to work.
We see AI agents, surveillance tools, and healthcare deployments all hitting hard limits today, and the common thread is that capability claims are outrunning real-world validation.
~4 min read · last 12 hours
In today's issue
01
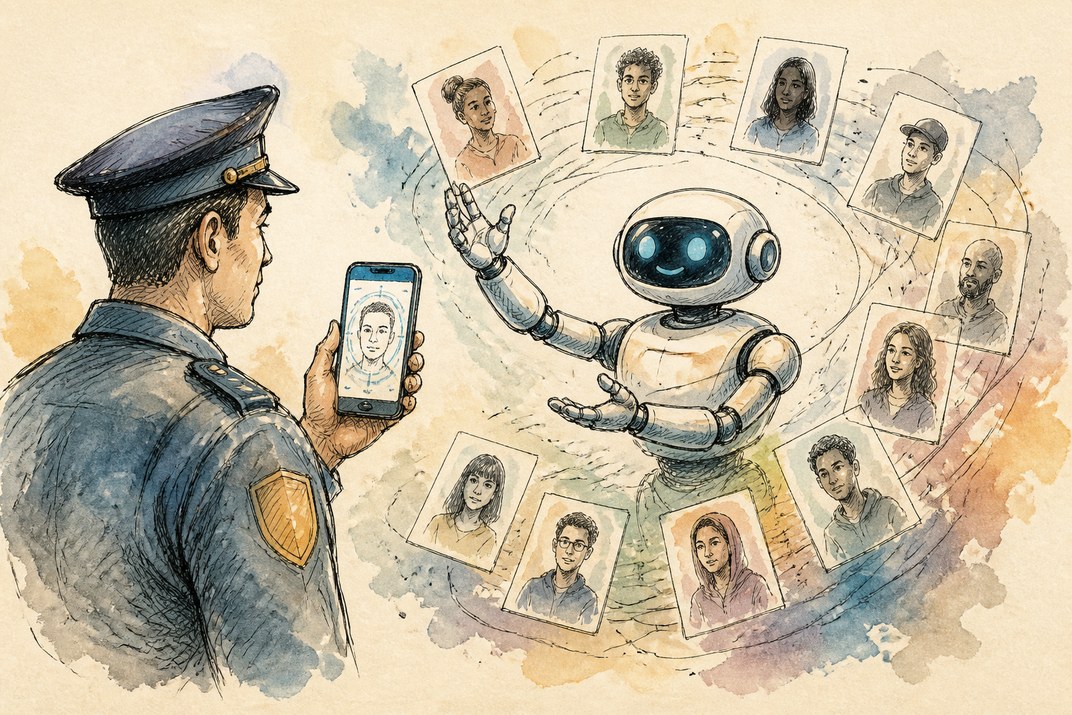
Clearview AI prototype uses Grok to build full profiles of people from a face scan
02
LLMs struggle with second-order social reasoning, not just first-order rules
03
Long-term memory in LLM agents rarely earns its cost in practice
04
LLMs reject factual errors inconsistently across languages
05
Listen Labs abandoned a $1.5B Series C to pursue Salesforce acquisition talks
Main story
Clearview AI prototype uses Grok to build full profiles of people from a face scan
InquiryIQ, an unreported Clearview prototype, combines facial recognition with an xAI language model to surface associates, social accounts, and personal details about identified individuals for law enforcement use.
Why it matters: This is the clearest public signal yet of LLMs being integrated directly into mass-surveillance pipelines, a development that raises immediate questions for any enterprise procuring AI tools with law enforcement or HR applications.
What to watch next: Watch for regulatory responses in the EU and US as the combination of facial recognition and LLM-generated profile synthesis moves from prototype to operational use in law enforcement.
Three stories today each show AI moving into high-stakes domains where the gap between capability and governance is widest, and where the business and ethical decisions are inseparable from the technical ones.
Medical queries handled per month by an auditable AI triage tool for nurses in India · arXiv cs.CL
Watch · On the feeds
The Equation That Might Destroy Itself
Two Minute Papers
GPT-6 Astra turned London into a game
OpenAI
The Signal
Today's items collectively signal that AI is moving fast into domains where errors and misuse carry serious consequences, from surveillance and healthcare triage to multilingual enterprise tools. The research findings on memory, social reasoning, and cross-lingual factual reliability all point the same direction: current evaluation frameworks are too narrow, and production deployments are being built on benchmarks that do not reflect real task performance. We think the most important near-term engineering discipline is not capability improvement but honest, domain-specific validation before deployment.
All the best, the KYFEX team
Quick hits
AI capabilities under the microscope: reasoning, memory, and trust
We see a clear pattern today: researchers are stress-testing where AI agents actually break down, from social reasoning gaps and unreliable long-term memory to factual inconsistencies across languages, and the findings should inform how confidently you deploy agents in production.
LLMs struggle with second-order social reasoning, not just first-order rules
A new benchmark shows that current models are trained to follow explicit social norms but fail at the harder task of reasoning about what others believe, expect, or intend in social situations.
Why it matters: If your agent needs to navigate ambiguous human interactions, such as customer service or negotiation, this gap is a real reliability risk that alignment fine-tuning alone will not close.
Long-term memory in LLM agents rarely earns its cost in practice
A cost-aware evaluation finds that standard memory benchmarks measure conversational recall, not whether remembered facts actually improve task outcomes, meaning most memory modules add latency without proven benefit.
Why it matters: Before adding a memory layer to your agent stack, demand task-outcome metrics rather than recall scores, or you are paying inference and storage costs for marginal gains.
LLMs reject factual errors inconsistently across languages
The SWORD benchmark uses Wikidata-based distortions to reveal that LLMs which correctly flag false claims in English often fail to do so in other languages, exposing hidden cross-lingual reliability gaps.
Why it matters: Any multilingual deployment that relies on the model to catch bad input data should be validated language-by-language, not assumed to generalise from English performance.
AI in the real world: surveillance, healthcare, and funding pivots
Listen Labs abandoned a $1.5B Series C to pursue Salesforce acquisition talks
The AI research startup walked away from a signed term sheet from Menlo Ventures, signalling that strategic acquisition by a large platform is now competing directly with independent growth as the preferred path for well-funded AI labs.
Why it matters: For AI teams evaluating build-vs-buy or partnership strategy, this is a data point that even well-capitalised startups are weighing platform integration over independence.
Build a full-stack web application that uses RAG capabilities to chat with your data. Learn to build a RAG application in JavaScript, using an intelligent agent to answer queries.
This course will teach you about integrating AI models your game and using AI tools in your game development workflow
Hugging Face · Free
Put it to work
Try this today
Audit an AI agent's memory layer for actual task value
You are a critical AI systems reviewer. I will describe an agent workflow that uses long-term memory. For each memory type listed, tell me: (1) what specific task outcome it improves, (2) what metric would prove that improvement, and (3) whether the benefit justifies the added latency and storage cost. Be direct and flag any memory use that only improves recall scores without improving task success.
Workflow description: [paste your agent workflow here] Memory types in use: [list them]
Why it helps: Today's research shows that most long-term memory evaluations measure recall, not outcomes, so this prompt helps you pressure-test your own stack before committing to the cost.
Before you ship it
The risk
Integrating LLMs with facial recognition and open-source data scraping, as shown in the Clearview prototype, creates profiling pipelines that can expose sensitive personal associations with no meaningful consent or oversight mechanism.
Do this
Before procuring or building any AI tool that combines identity signals with LLM-generated inference, require a documented data-minimisation and legal-basis review covering every data source the model can reach.
Ready to ship AI, not just read about it?
KYFEX designs and builds production AI for teams that need it working, not just demoed. Tell us what you're working on and we'll bring the engineering.